A single default model is wrong for half your tasks — overkill for the quick ones, underpowered for the hard ones — but the choice is hidden in settings, if it exists at all, and most chat pickers that do exist name the models without saying what they cost.
← Back to patterns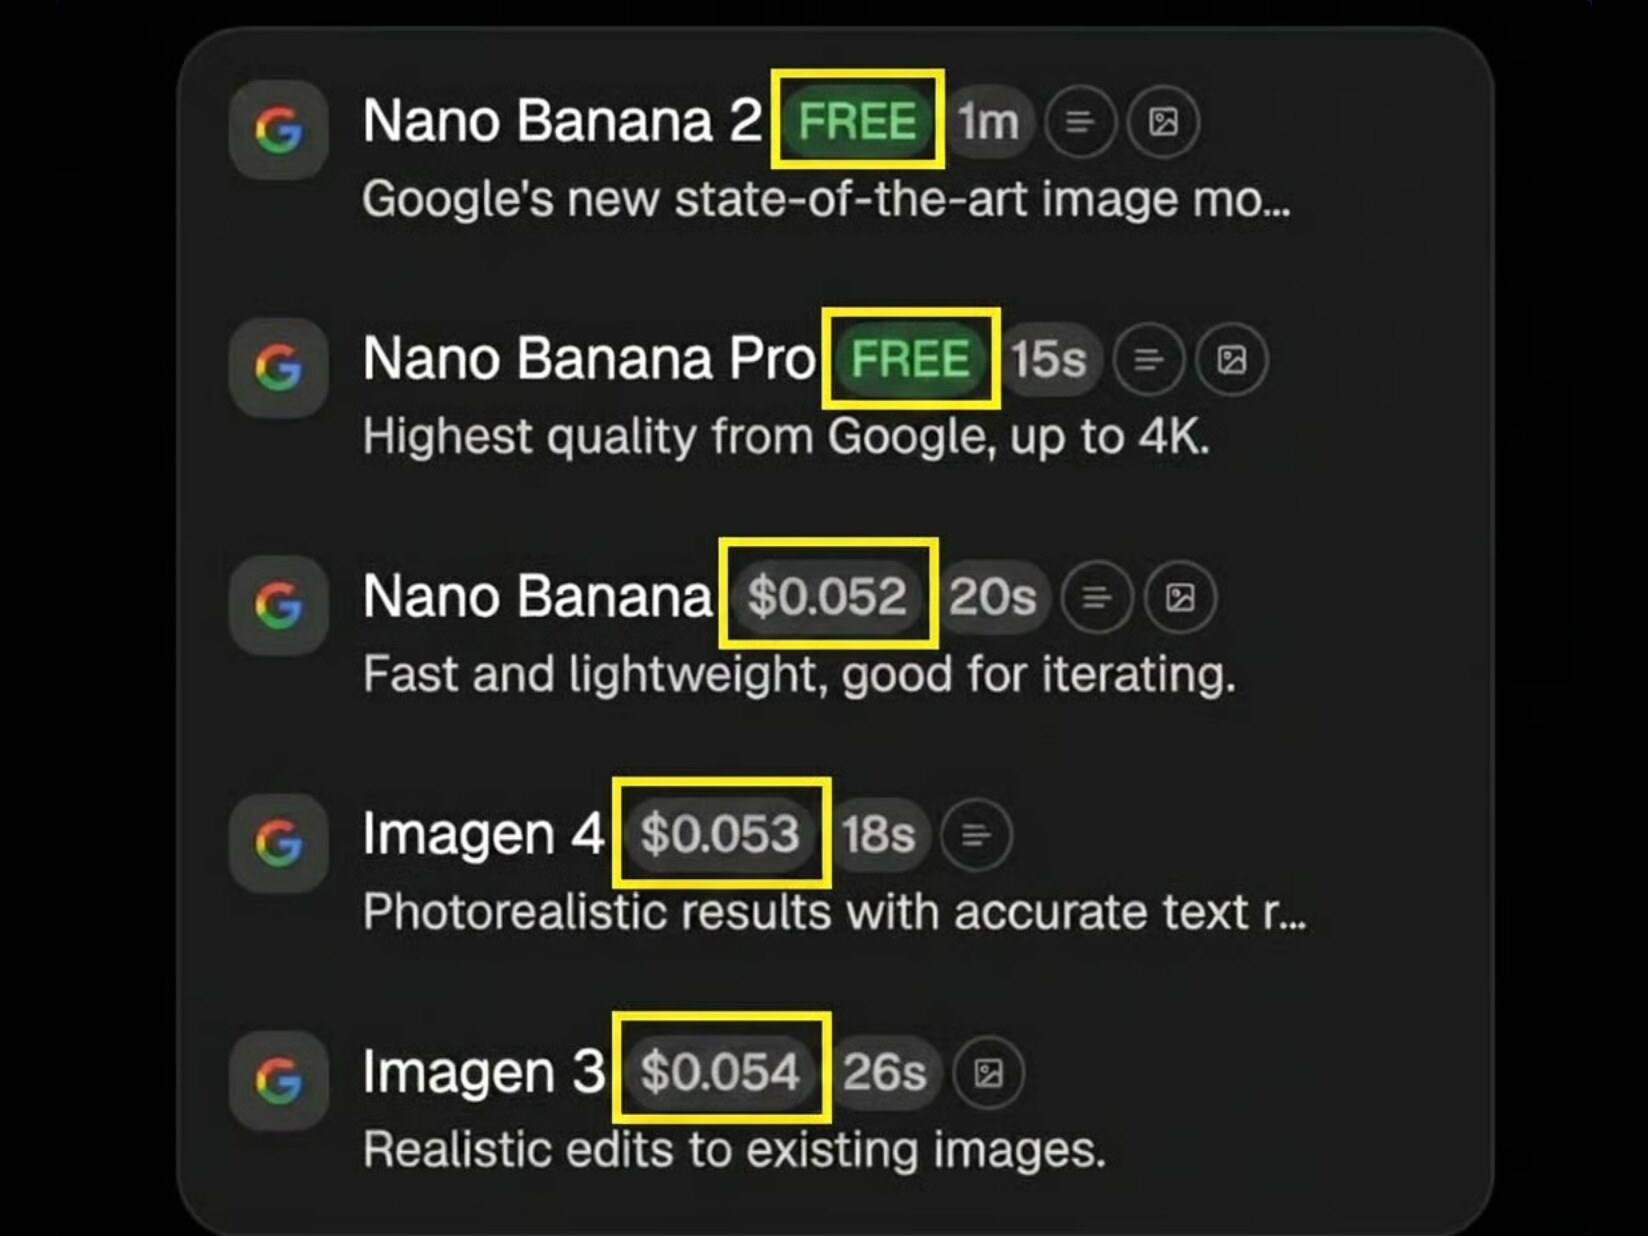
Memory, Context & Boundary
Model Selector
Pick the model for the task, see the trade-off
A single default model is wrong for half your tasks — overkill for a quick reword, underpowered for a hard debug — yet the choice is hidden in settings, if it exists at all. Model Selector surfaces the engine as a per-task control: a small set of named models with their speed, cost, and strengths, switchable in one move, with a sensible default so picking is optional, not required. Consumer chat names its models again — ChatGPT's menu now offers GPT-6 and GPT-5.6 Sol beside a Thinking slider from Instant to Pro — but shows only half the trade-off: names and effort, never price, and under GPT-6 the menu does not say whether Sol or Astra is answering. That gap is the case for the pattern: chat pickers rarely put cost beside the choice, media tools such as FLORA already show it on every row, and wherever someone pays for every call, cost is the half that has to stay visible.
Metaphor
Gearbox
Interaction
Per-Task Model Pick, Fit Indicator, Cost/Speed Estimate
Use case
Mixed-Difficulty Workloads, Cost Control, Latency-Sensitive Tasks
Failure mode
One-Size Model
Control mechanisms
Model Cards · Default + Override · Speed/Cost/Capability Meters · Task-Fit Hint
Reference examples
FLORA Model picker · Notion Agent Model picker · ChatGPT Model menu + Thinking slider · Claude Model + effort selector · Cursor Model picker · OpenRouter Model catalog
Interactive Example
The chat default and the pattern, against each other on the same task. The demo is the comparison.
One model for every task is the wrong default for most of them.
Tasks aren't one size. Rewording a sentence and debugging a race condition want completely different engines — and most chat pickers now name a few, but not what each one costs, and an automatic mode can switch engines without saying which one answered. So half your work is either paying for power it doesn't need or starved of the power it does.
Model Selector pulls the engine into the open as a per-task control: a few named models with their speed, cost, and strengths on the card, a sensible default, and one move to switch. The trade-off — fast and cheap vs slow and capable — becomes the user's to make, not a silent setting.
The right model is the cheapest one that still clears the bar — and only the user knows where the bar is for this task.
DOPE Lens
How this pattern improves AI interaction quality.
DirectabilityPrimary
Pick the model per task or set a default — fast and cheap, or slow and capable
Observability
The active model and its trade-offs — speed, cost, context, strengths — are visible before you run
Predictability
The same model gives the same class of result; switching is explicit, never a silent swap
Explainability
Each model card states what it is good at and what it trades away, so the pick is informed
Fit
Where it earns its place.
Use it
when
when
Tasks vary from trivial to hard, so a single default model is wrong for most of them — and the cost/speed/capability trade-off should be the user's to make.
Avoid
when
when
One model genuinely serves every task, or the audience only ever trades speed for depth — a single effort dial covers that without asking anyone to compare engines.
In the wild
Where this pattern already ships.
Real implementations from products users already know. Each entry shows how the pattern got applied — what shipped, where it sits in the product, what it traded off.
FLORA · Model picker
FLORA
Each row of FLORA's model picker shows a cost, a duration pill and a one-line strength such as "Fast and lightweight, good for iterating", and new nodes reuse the last used model. By default the cost is a four-step flower meter; a Preferences toggle swaps it for dollars per generation, pictured here. The list is a large searchable catalog, not a small named set, and the docs never label the duration pill.
Visit FLORA ↗
Notion Agent · Model picker
Notion
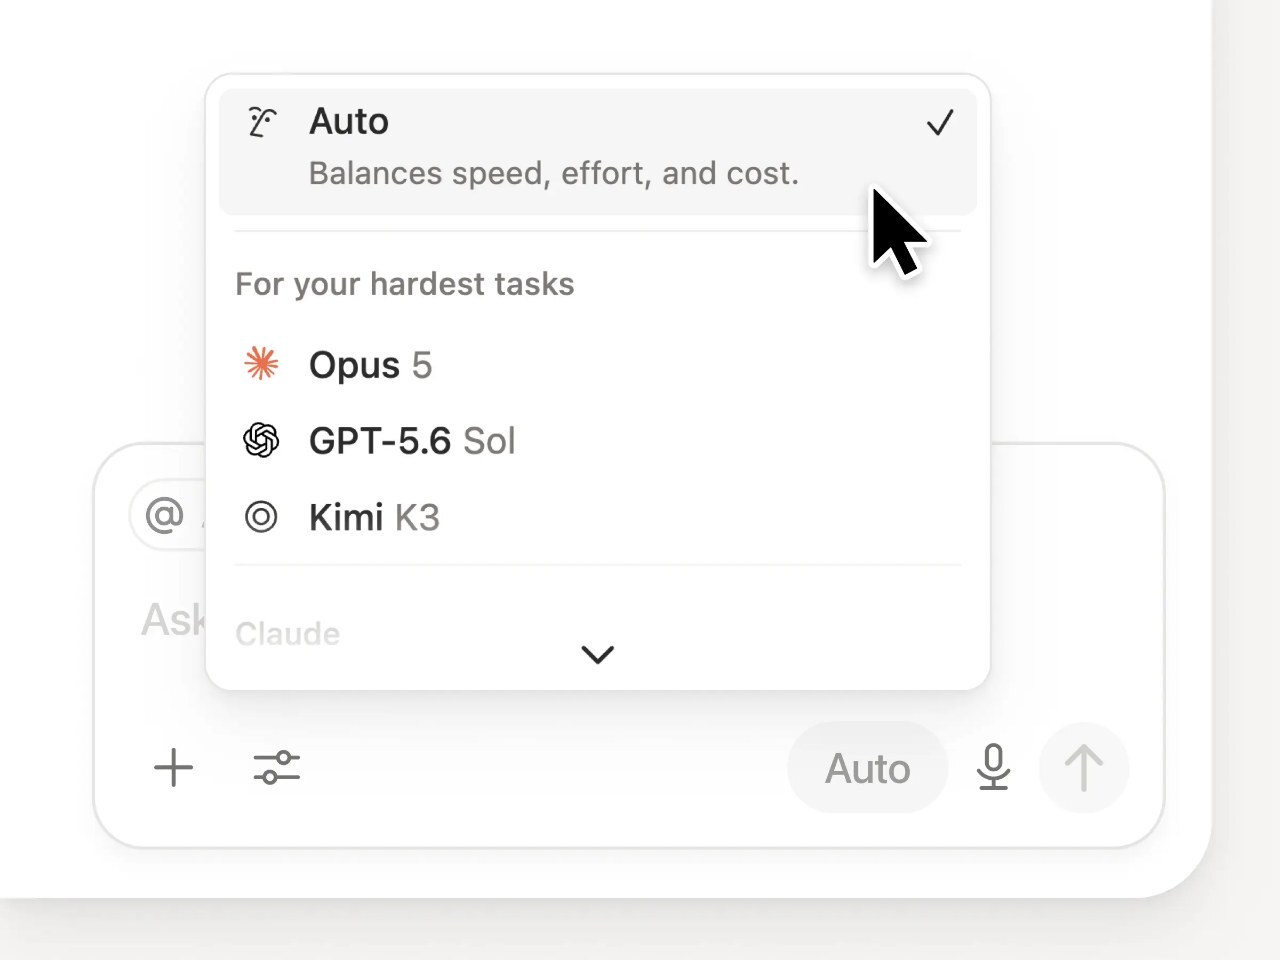
Notion Agent chat defaults to Auto; selecting it opens a model picker that, per August 2026 release notes, leads with a shortlist. Hovering a model compares speed, intelligence and cost; the pick holds for that chat. But Notion's help pages name no other measure and don't say the picker shows credits, though manual picks draw on a different pool. Owners control what can be picked; dollars per task sit on a separate Knowledge Board. Pictured: the picker with Auto and a shortlist; the hover state is not shown.
Visit Notion ↗
ChatGPT · Model menu + Thinking slider
OpenAI
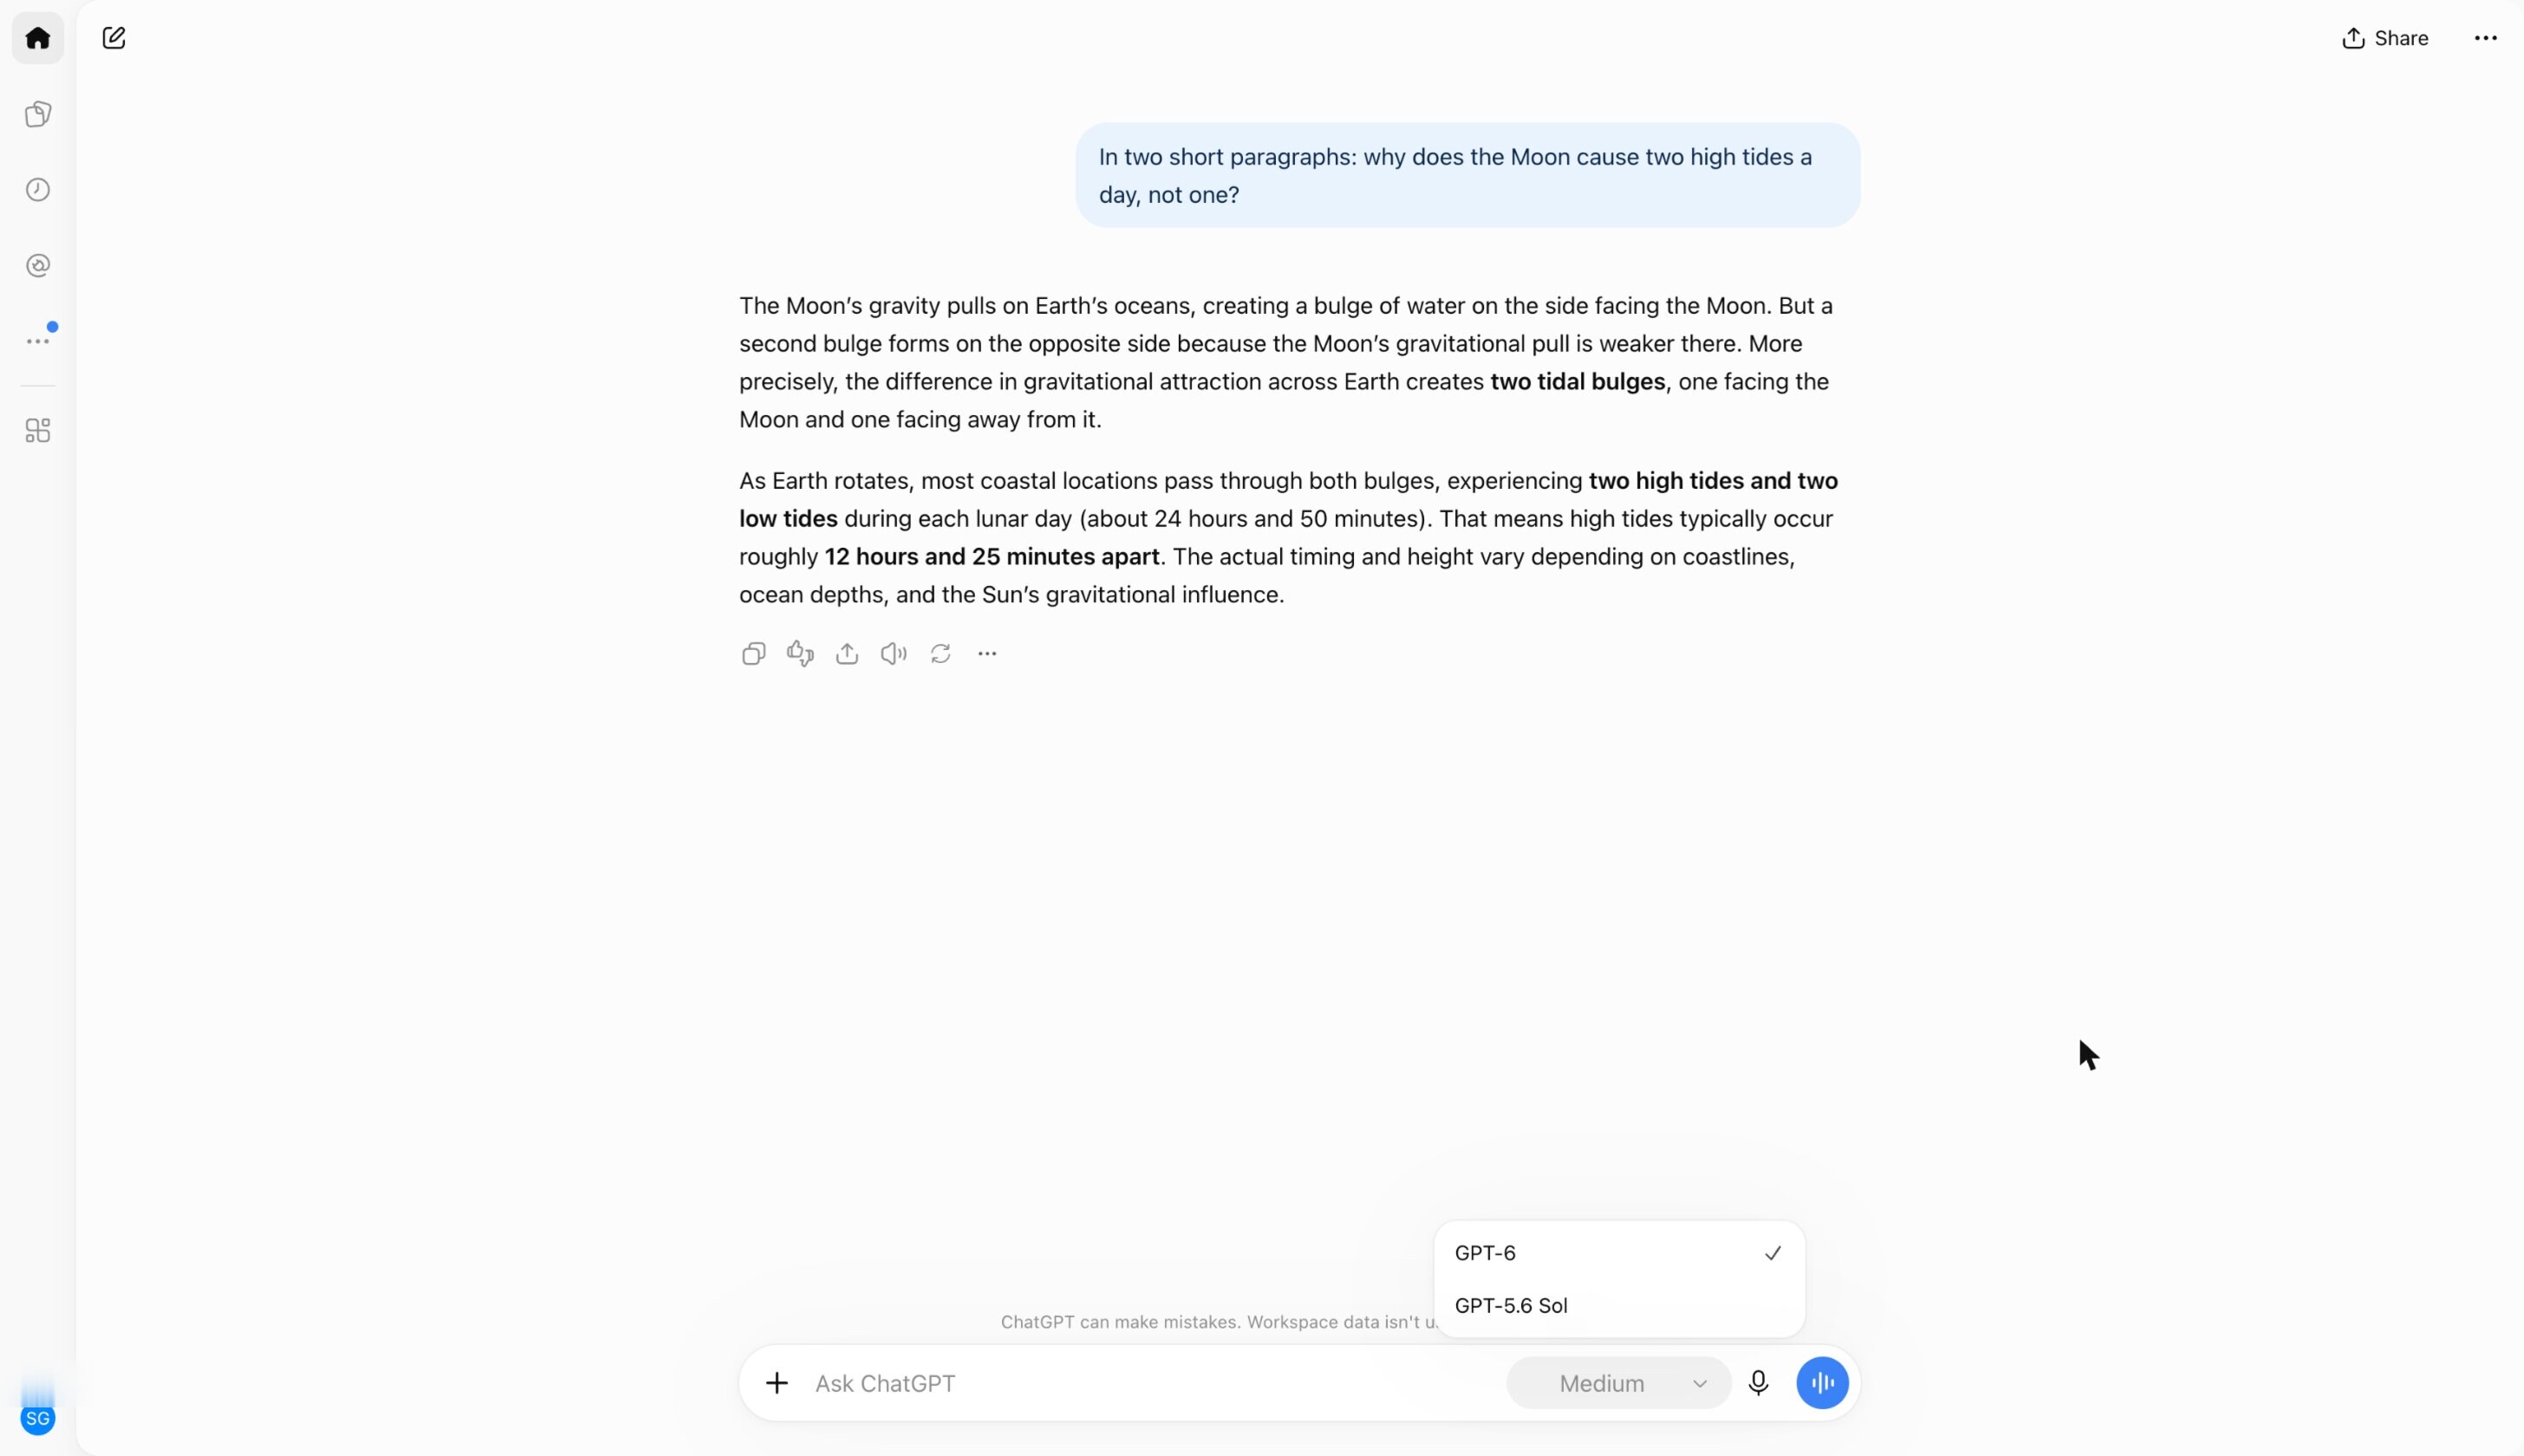
Named models are back in the menu — GPT-6 replaced Latest, GPT-5.6 Sol stays selectable — beside a Thinking slider: Instant, Medium, High, Extra High, Pro. Under GPT-6, Sol runs the first four rungs and Astra runs Pro, though the menu just says GPT-6. No cost is shown, and when a Thinking limit runs out ChatGPT may carry on with another model.
Visit OpenAI ↗
Claude · Model + effort selector
Anthropic
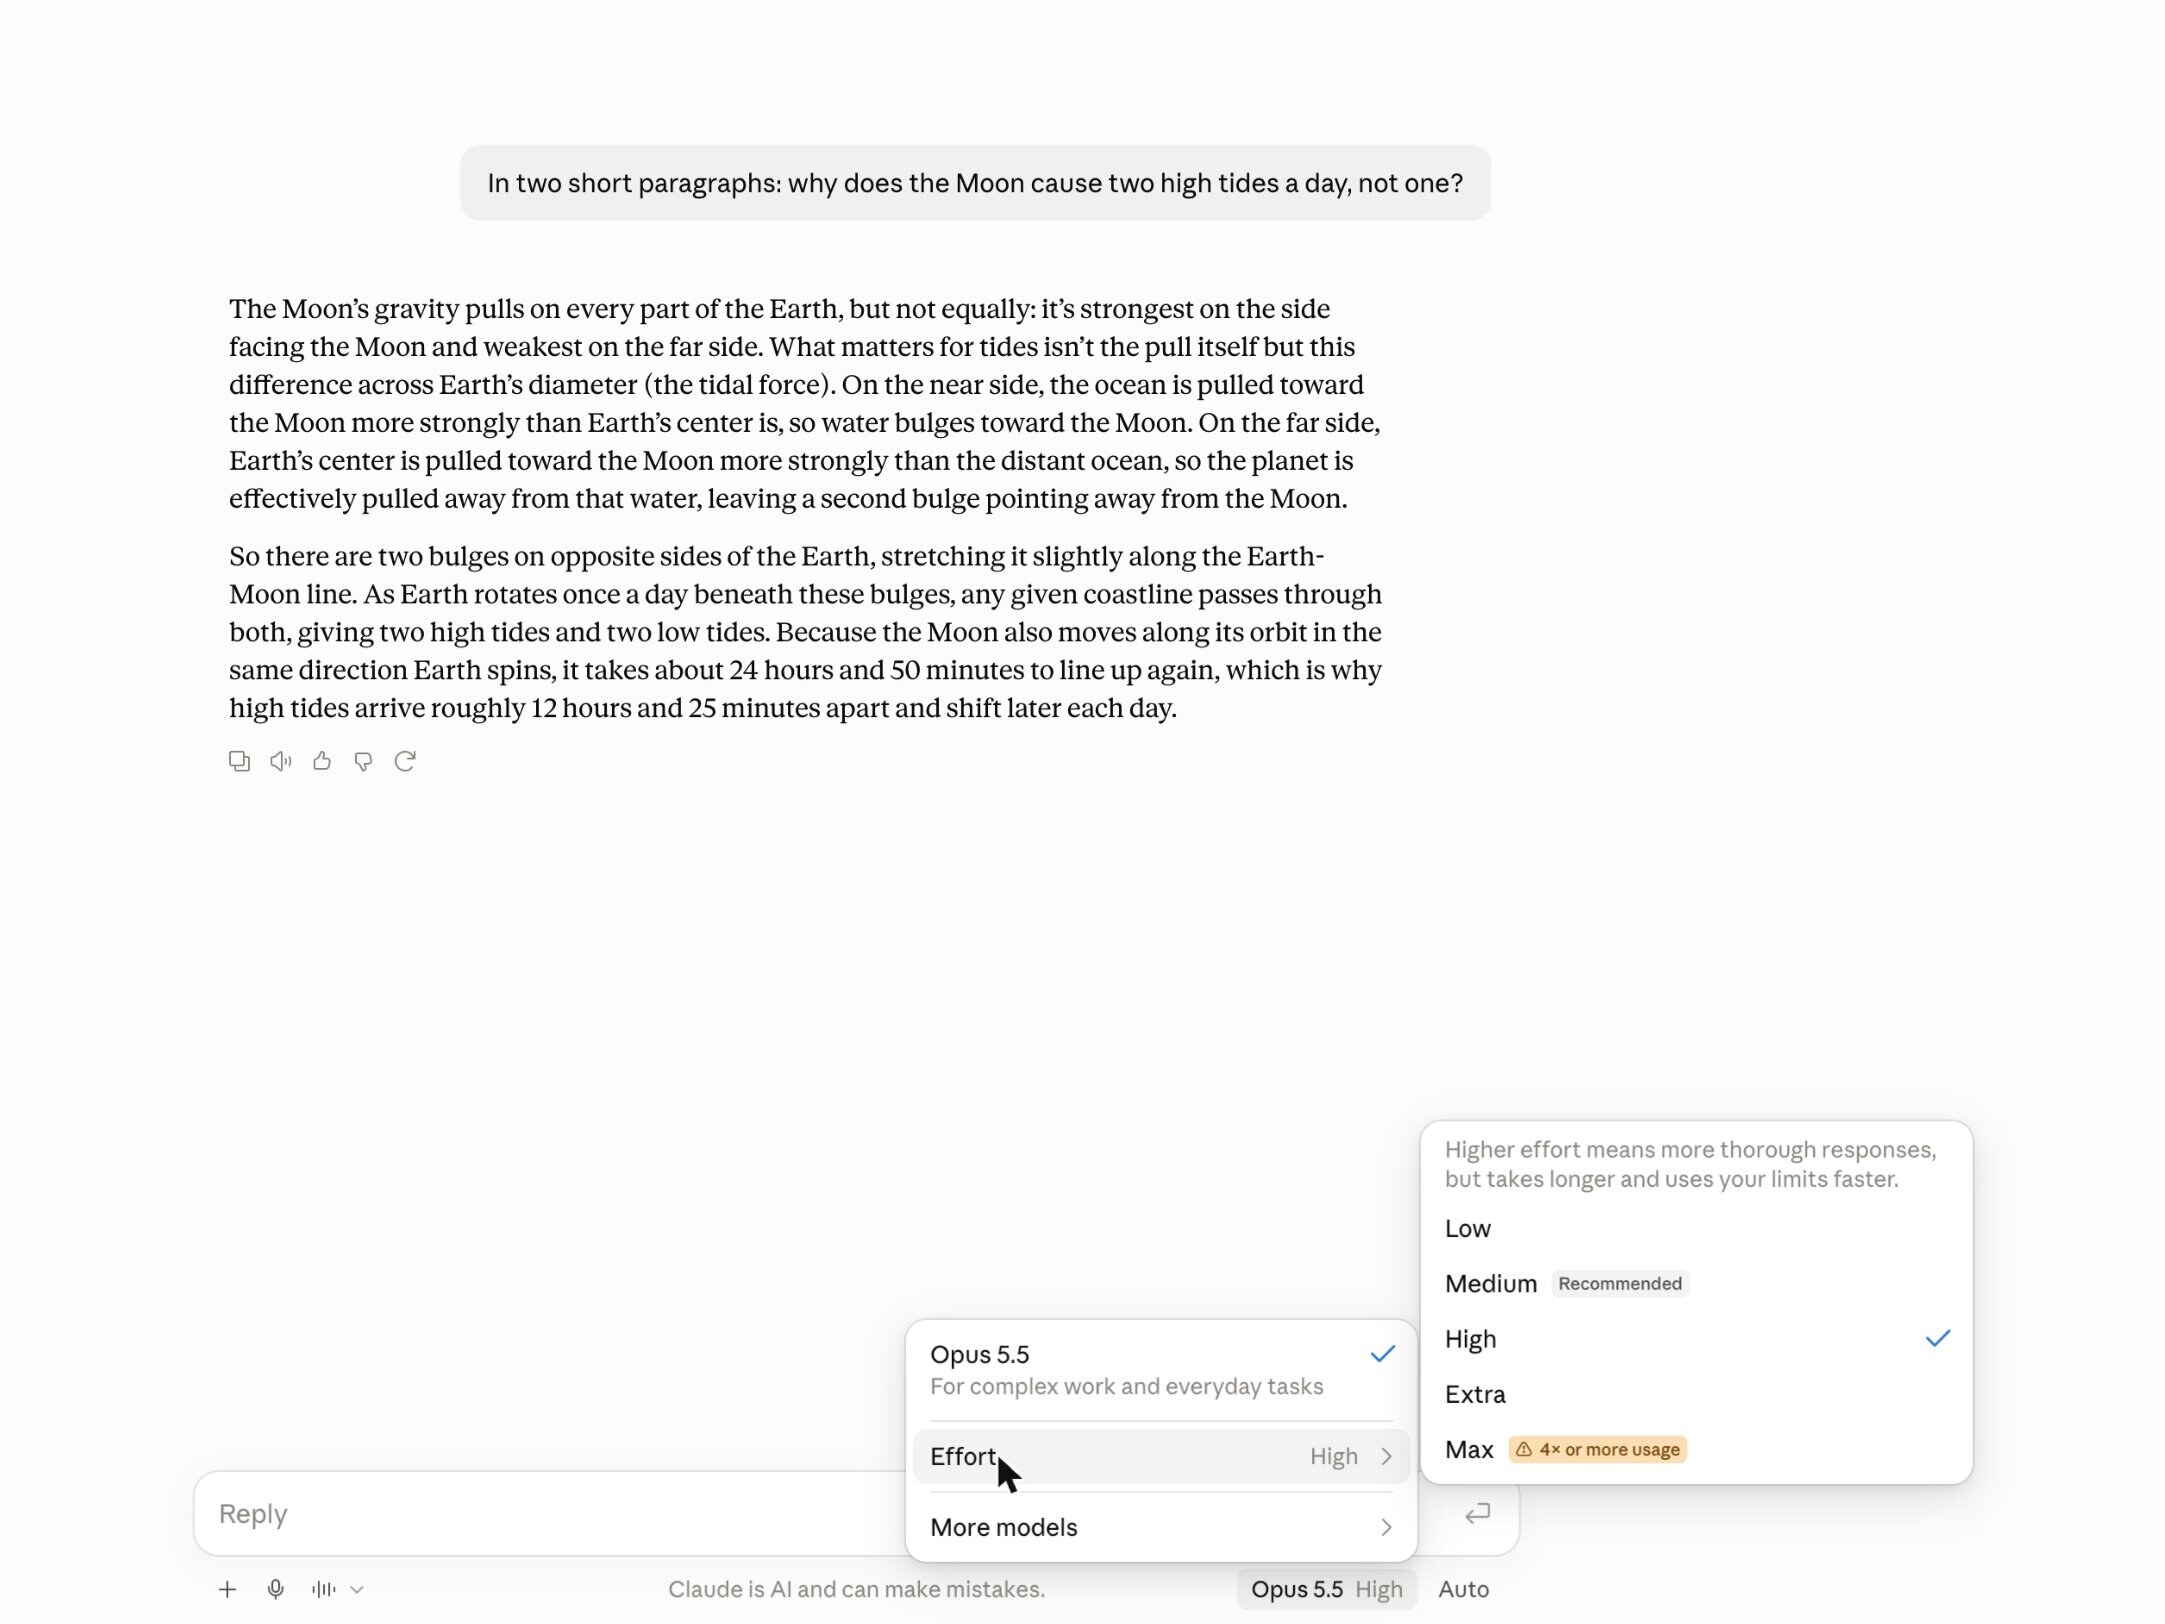
Named models (Haiku, Sonnet, Opus, Fable) sit in a menu next to the send button, now paired with an effort selector running Low to Max; each model's recommended level is marked Default. The help article states the trade-off: more thorough responses, but slower, and you reach your usage limits faster. Cost stays relative, in tokens and limits: the article names no price and does not say the menu shows the trade-off.
Visit Anthropic ↗
Cursor · Model picker
Cursor
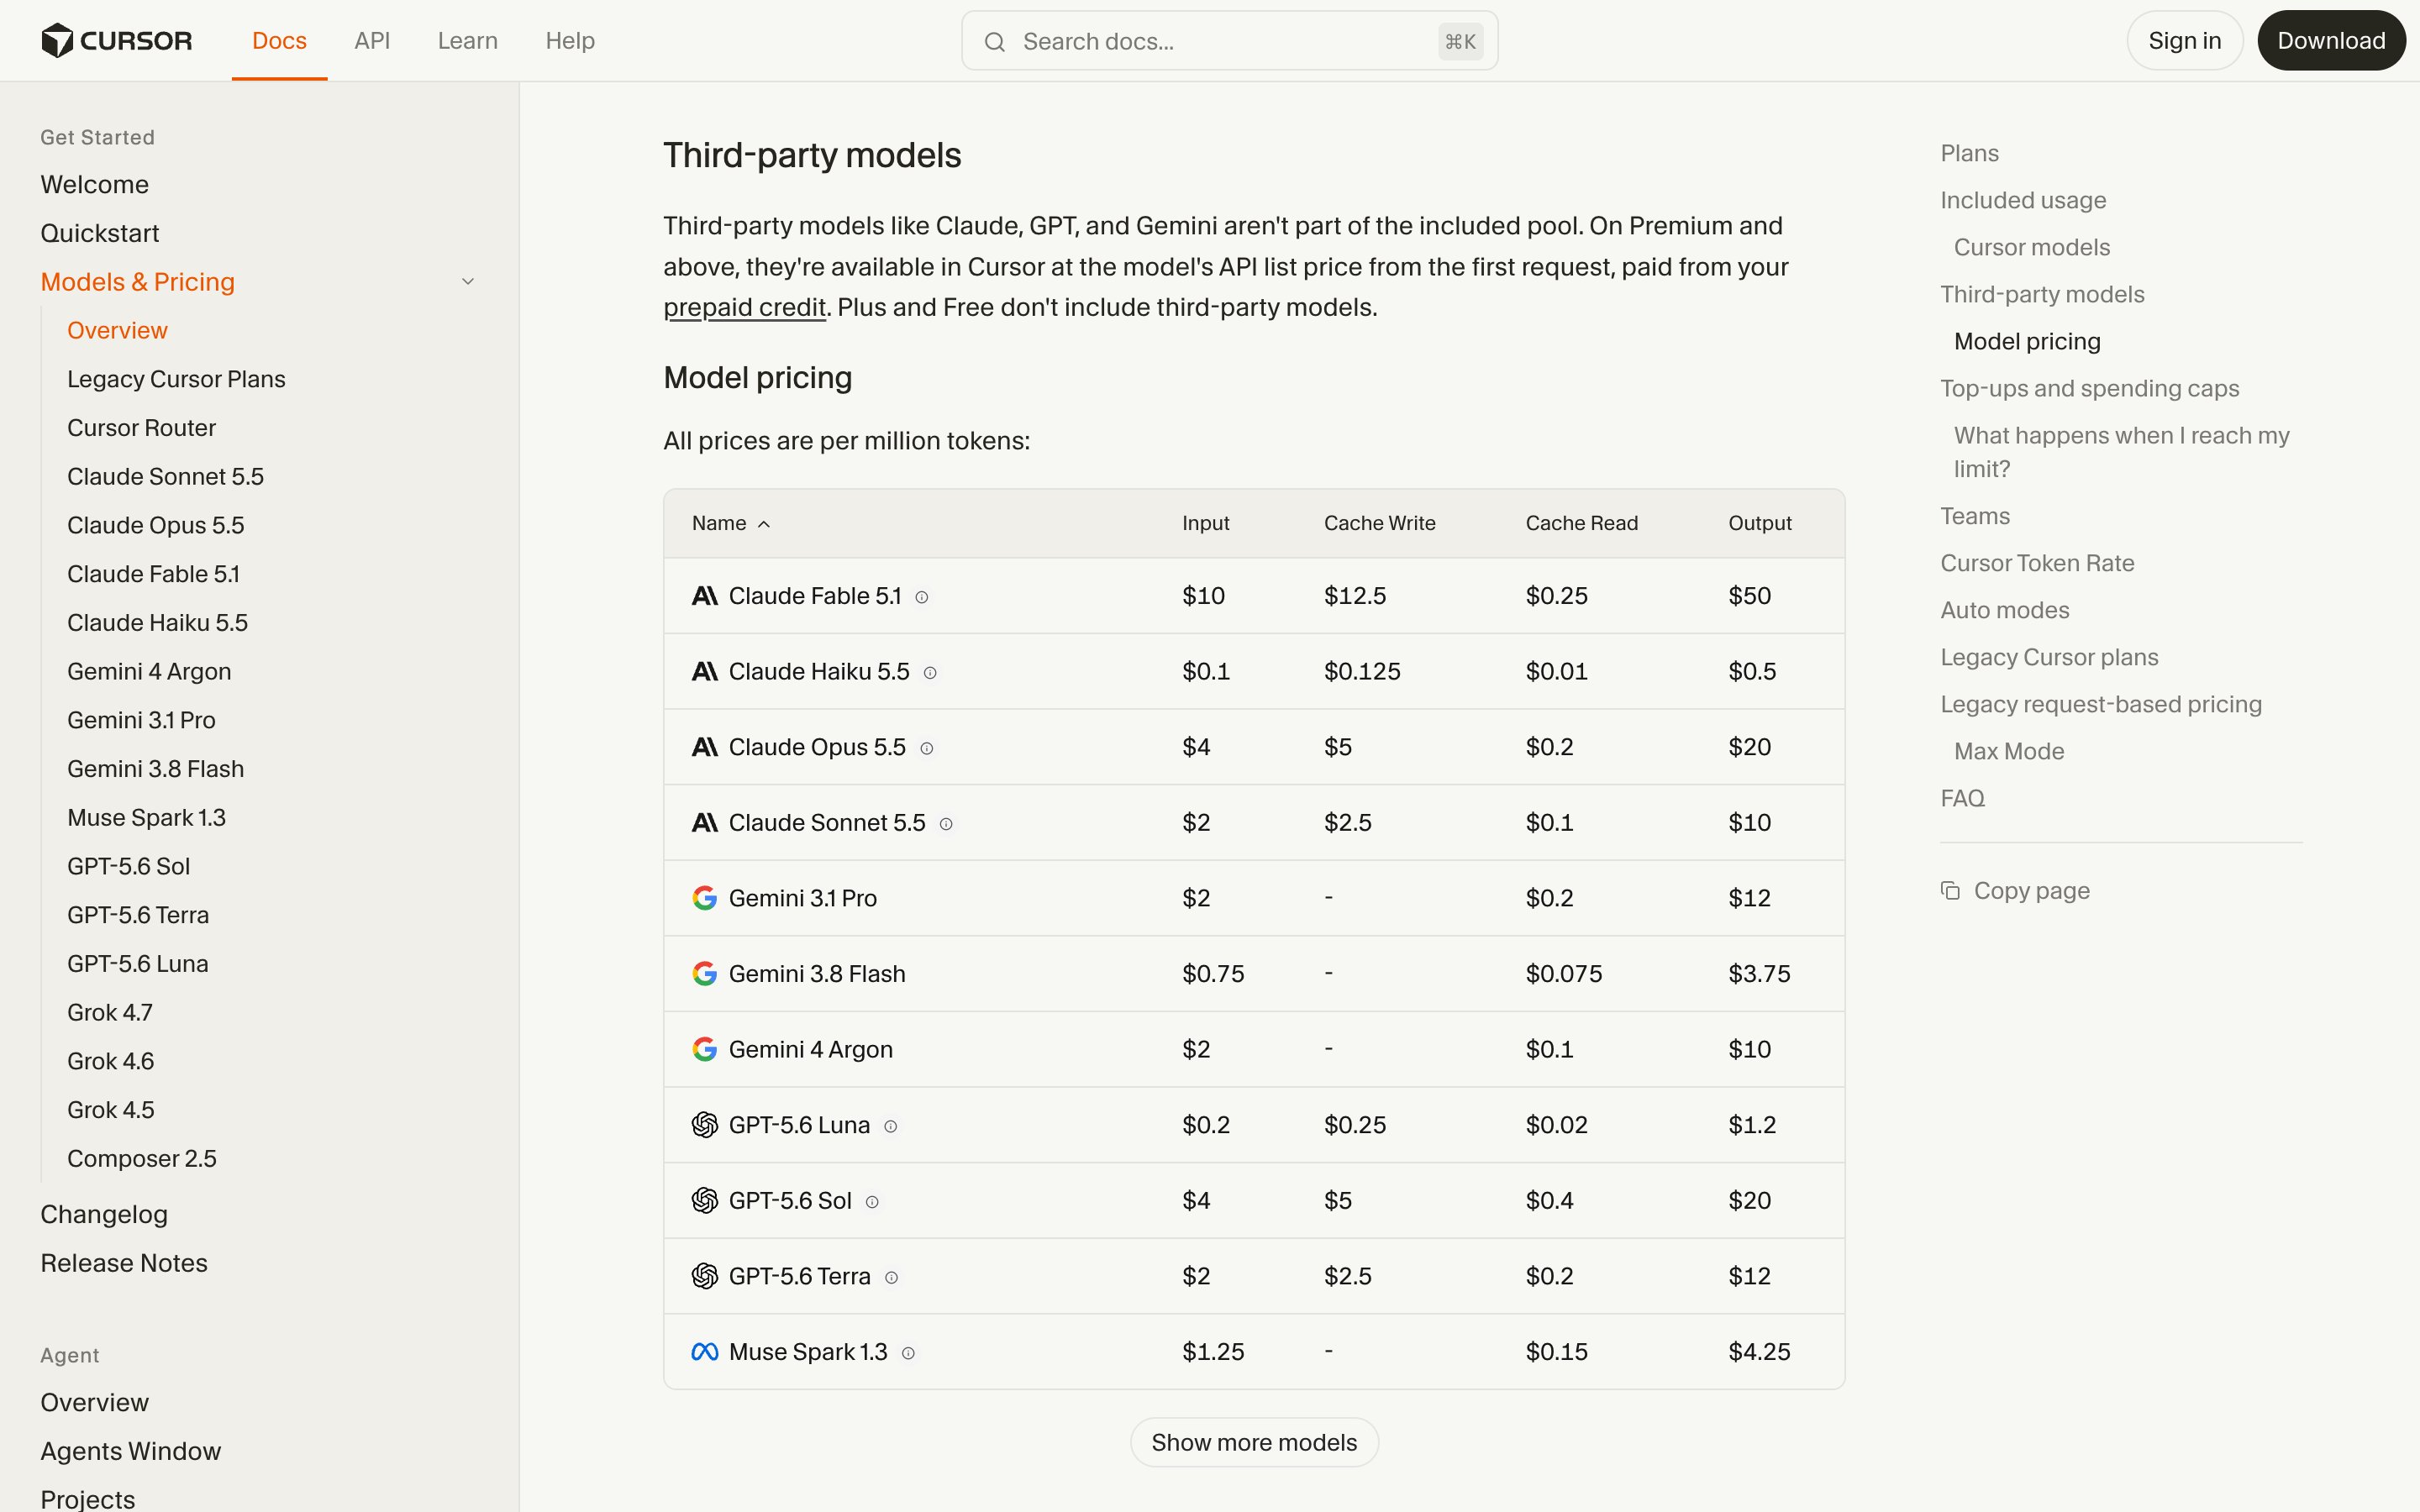
From Premium up the picker adds third-party models and Auto, which on individual plans runs in Cost mode only; Plus gets Cursor's own four models at fixed settings, and a Free account's picker showed one model and "Upgrade to unlock more models". On Teams and Enterprise, Cursor Router adds Balance and Intelligence modes and by default hides which model it routed to. Per-model prices sit on this docs page, away from the picker.
Visit Cursor ↗
OpenRouter · Model catalog
OpenRouter
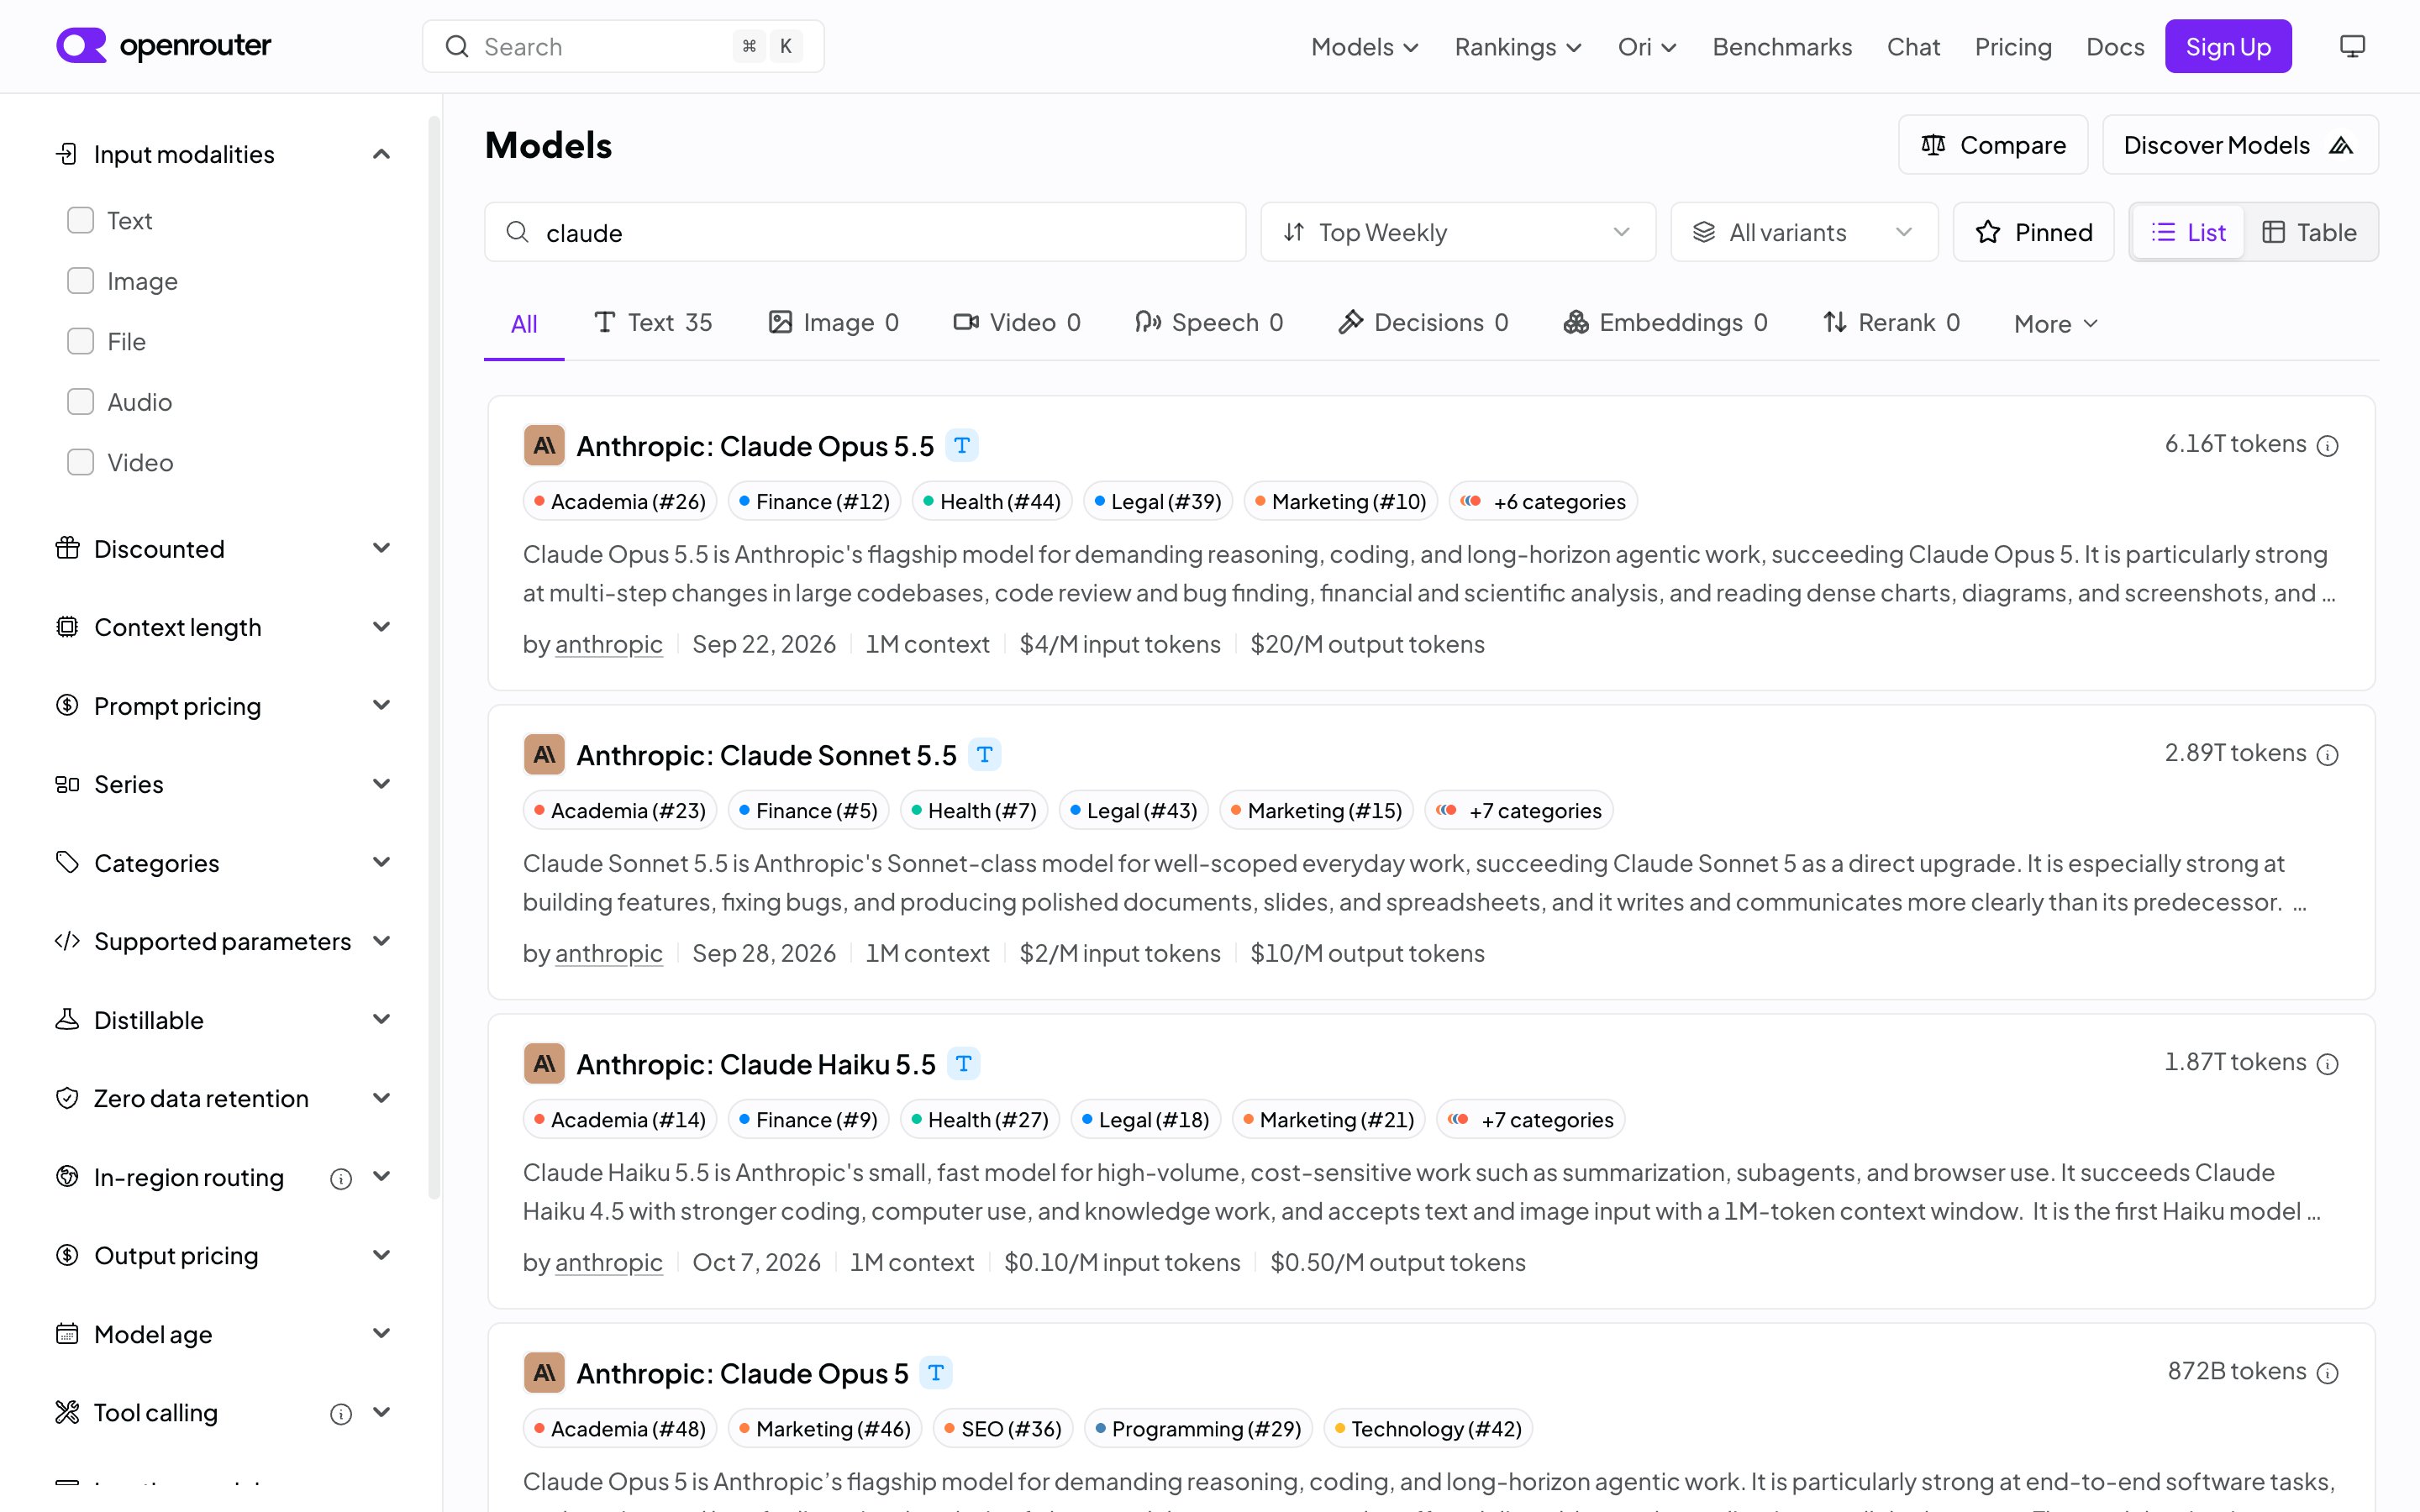
Price, context length, and benchmark rank across the catalog; latency, throughput, and uptime per provider on each model page, plus a compare view and request-time routing modes — Balanced, Nitro, Exacto. The fullest trade-off surface anywhere, but it lives on browsing pages rather than inside a single pick.
Visit OpenRouter ↗
Research Frame
Why this pattern exists, and where it breaks.
Surface the model as a per-task control — a small set of named models with their speed, cost, and strengths, switchable in one move — with the trade-off on screen at the moment of the pick, not on a pricing page.
Chat picks one model behind the scenes, and the pickers chat does ship show only half the trade-off — ChatGPT's menu names GPT-6 and GPT-5.6 Sol beside a Thinking slider, but no price, and it says GPT-6 whether Sol or Astra is answering.
Too many models is choice overload, and exposing raw model names without their trade-offs just moves the guesswork onto the user.
Common questions
What people ask about this pattern.
When should I use the Model Selector pattern?
+
Tasks vary from trivial to hard, so a single default model is wrong for most of them — and the cost/speed/capability trade-off should be the user's to make.
When should I avoid the Model Selector pattern?
+
One model genuinely serves every task, or the audience only ever trades speed for depth — a single effort dial covers that without asking anyone to compare engines.
What problem does Model Selector solve?
+
A single default model is wrong for half your tasks — overkill for the quick ones, underpowered for the hard ones — but the choice is hidden in settings, if it exists at all, and most chat pickers that do exist name the models without saying what they cost.
Why is chat the wrong fit for this?
+
Chat picks one model behind the scenes, and the pickers chat does ship show only half the trade-off — ChatGPT's menu names GPT-6 and GPT-5.6 Sol beside a Thinking slider, but no price, and it says GPT-6 whether Sol or Astra is answering.