AI systems prefer confident hallucination to honest refusal — users discover the limit by being misled.
← Back to patterns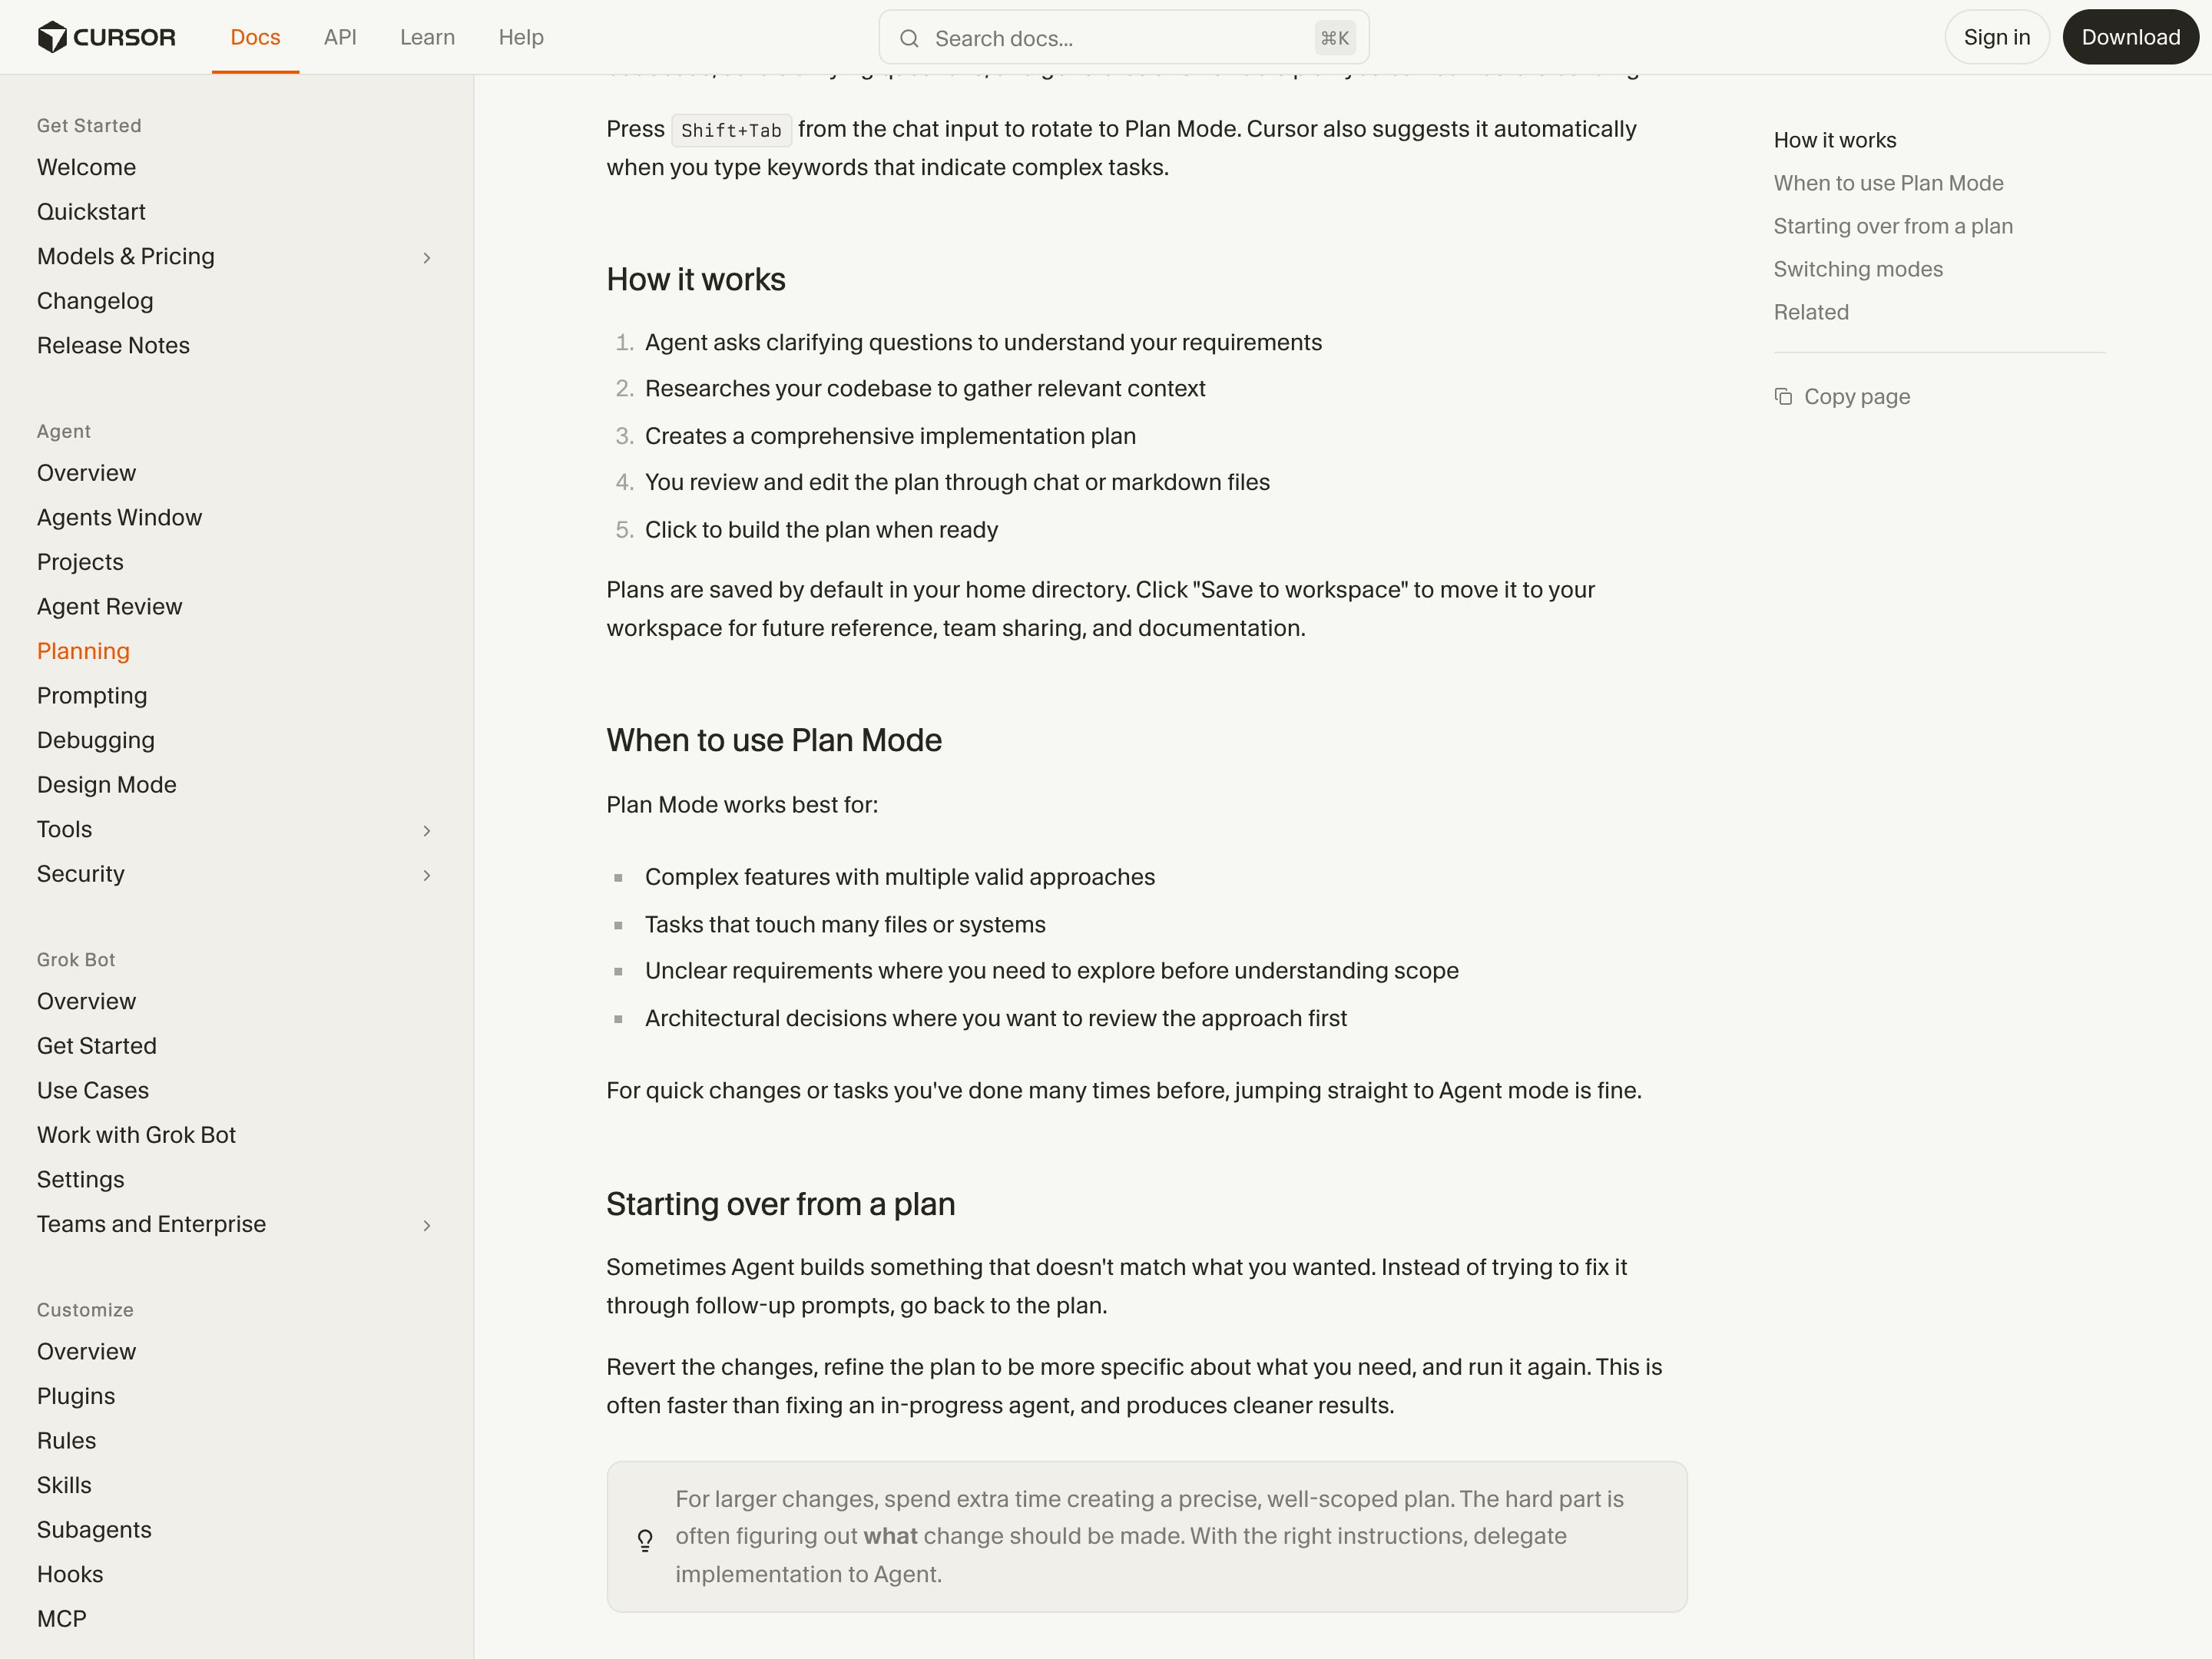
Guidelines for Human-AI Interaction (HAX Toolkit, G1-G18) People + AI Guidebook Explainable AI in Chat Interfaces
Trust & Verification
EmergingCapability Boundary
Honest about what it cannot do — before it tries
Before running, the system declares which parts of the task it can confidently handle and which it will refuse or substitute. Honest pre-flight disclosure beats confident hallucination — and offering a workaround beats a flat refusal.
Metaphor
Spec Sheet
Interaction
Pre-flight Disclosure, Workaround Offer
Use case
Tasks Near Model Limits, Compliance-Sensitive Work, Reducing Hallucination
Failure mode
Helpful Hallucination
Control mechanisms
Can-Do List · Cannot-Do List · Workaround Path · Proceed-with-Limits
Reference examples
Cursor Plan Mode · Devin Confidence Scores · Microsoft Copilot Studio
Interactive Example
The live side-by-side is the comparison.
This prototype already contains the contrast between chat and the pattern response. It stands as the primary comparison surface for this page.
Confident, or correct. Pick before you run.
AI systems are tuned to a yes-and register, so they prefer a plausible-sounding answer to an honest refusal — and the user discovers the limit only by being misled past it. By then the tokens are spent, the boundary is invisible, and trust is already damaged.
Capability Boundary moves the disclosure before the run: a pre-flight sheet declaring what the system will do, what it will refuse, and a reason plus a workaround for each thing it can't. Knowing which part of the answer to trust and which to verify yourself is worth more than a uniformly confident output that hides where it breaks.
An assistant that tells you its limits before it runs is more useful than one that hides them behind a fluent answer.
DOPE Lens
How this pattern improves AI interaction quality.
Observability
The system declares its scope for this task before any tokens are spent
Directability
Choose to proceed within the limits, supply the missing input, or abandon the task
Predictability
Users know what part of the answer to trust and what to verify themselves
Explainability
Each refused capability comes with a reason and a workaround when one exists
Fit
Where it earns its place.
Use it
when
when
Limits are real and silent failure (confident hallucination) is costlier than honest refusal.
Avoid
when
when
The model is reliably within capability for the task — disclosure adds noise without value.
In the wild
Where this pattern already ships.
The pattern is shipping but still maturing across products. Entries below show how different teams have approached it; expect variation as the space settles.
Cursor Plan Mode
Cursor
Plan Mode (Shift+Tab or the mode picker) asks clarifying questions, researches the codebase and writes an editable Markdown plan with file paths and to-dos before Agent writes any code — the slot where a capability sheet would sit. Cursor documents no can't-do list in it: the questions are there to understand your requirements and improve the plan, and when a build misses, the docs say revert, refine the plan and run again.
Visit Cursor ↗
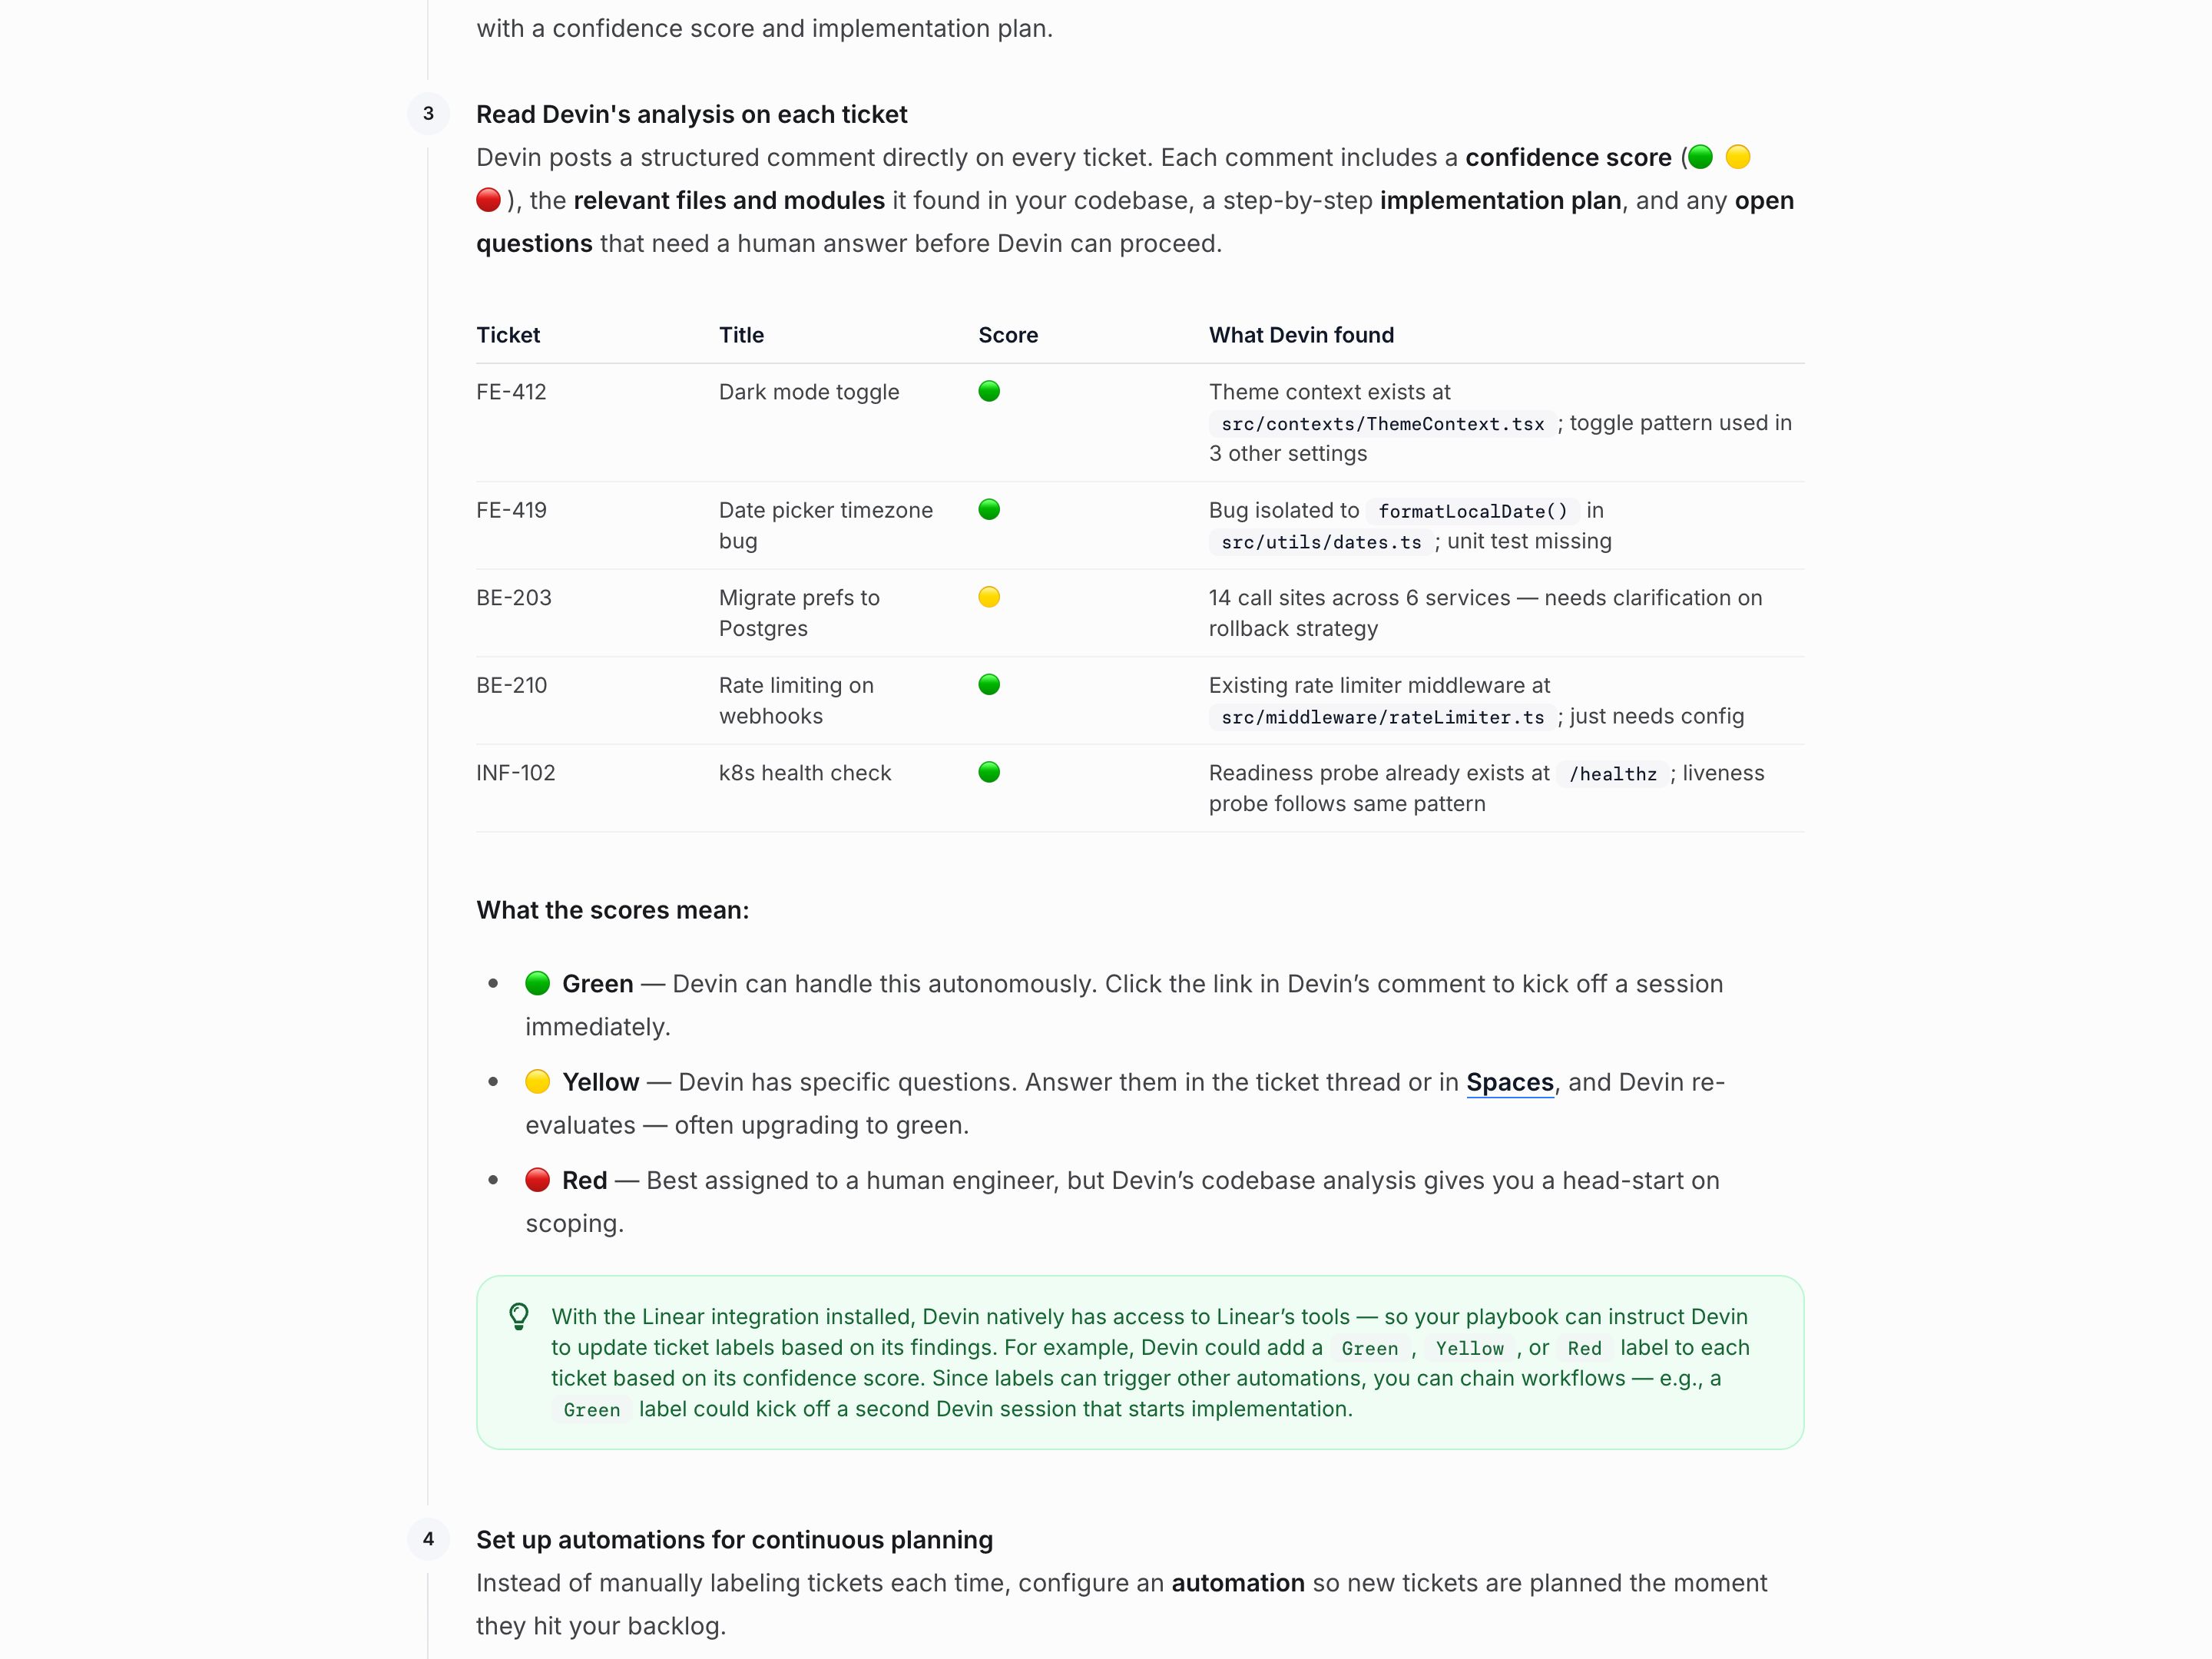
Devin Confidence Scores
Cognition
In Linear, Devin's !plan playbook (the default for new connections) scopes a ticket without writing code and posts a comment with a confidence score, the files it found, a step-by-step plan and any open questions. Green means Devin can do the work autonomously, yellow that it has specific questions, and red that the ticket is best assigned to a human engineer, with Devin's analysis as a head start. Answer the questions and Devin re-evaluates, often moving the ticket up to green. One score grades the whole ticket; it does not mark which parts Devin will and won't do.
Visit Cognition ↗
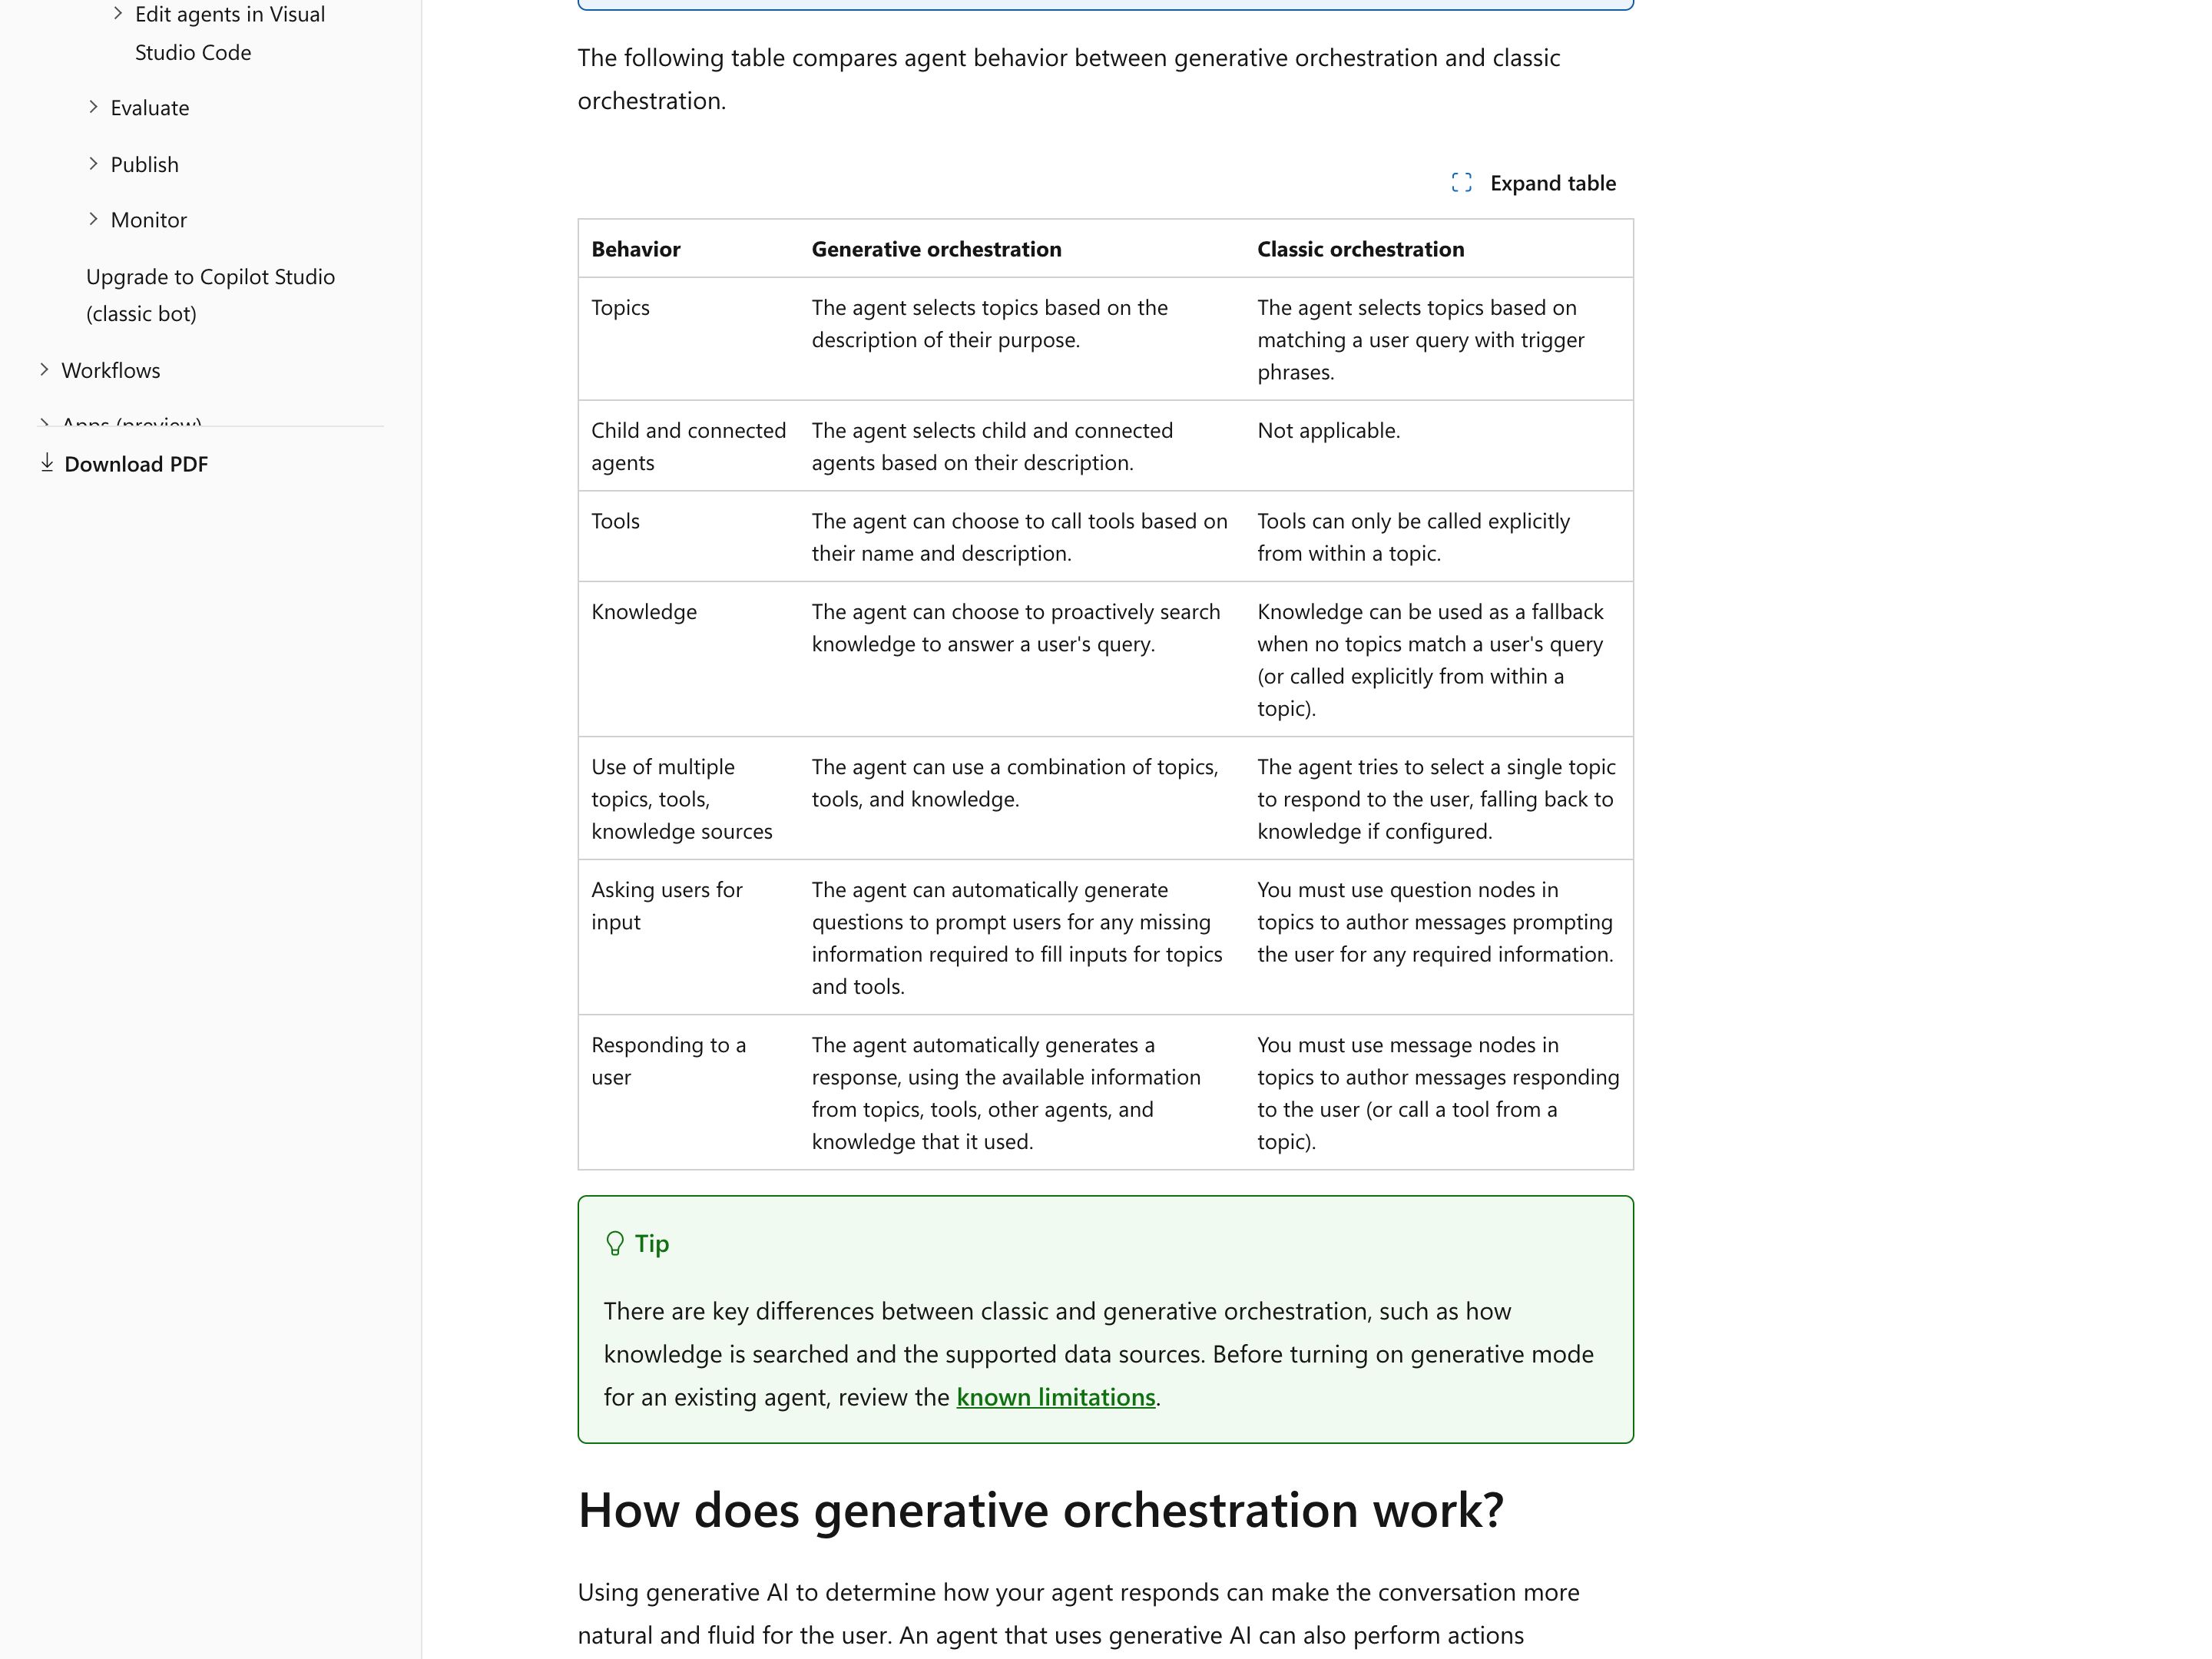
Microsoft Copilot Studio
Microsoft
In Copilot Studio's standard harness, now reached through Other ways to build or Open classic experience, new agents default to generative orchestration, which writes its own questions for any input a topic or tool still needs before calling it — the ask-for-the-missing-piece half. Microsoft suggests adding what a topic or tool can't do to its description ("It doesn't get weather forecasts for future days"), but the orchestrator reads descriptions to choose what to call, and no documented surface shows them to the user. What users see up front is the Conversation Start greeting, which builders can edit to introduce the agent and its capabilities; the "did you mean" Multiple Topics Matched topic isn't called under generative orchestration.
Visit Microsoft ↗
Research Frame
Why this pattern exists, and where it breaks.
Surface a pre-flight capability sheet: what the system will do, what it will refuse, and how the user can supply the missing piece.
Chat encourages a "yes-and" register that hides limits behind plausible-sounding answers.
Over-cautious capability lists become friction theatre and erode trust through false modesty.
Common questions
What people ask about this pattern.
When should I use the Capability Boundary pattern?
+
Limits are real and silent failure (confident hallucination) is costlier than honest refusal.
When should I avoid the Capability Boundary pattern?
+
The model is reliably within capability for the task — disclosure adds noise without value.
What problem does Capability Boundary solve?
+
AI systems prefer confident hallucination to honest refusal — users discover the limit by being misled.
Why is chat the wrong fit for this?
+
Chat encourages a "yes-and" register that hides limits behind plausible-sounding answers.
Grounded in Research
Not just opinion.
The papers, guidelines, and usability studies this pattern rests on.
Saleema Amershi et al.
Microsoft Research · 2019 · refreshed 2026-07
The canonical 18-guideline taxonomy for human-AI interaction. Strongest anchors: G9 efficient correction, G11 why-did-it-do-that, G17 global controls. Its three zero-coverage guidelines — G6 bias mitigation, G14 cautious updates, G18 change notification — became this library's Bias Flag and Model Changelog patterns in July 2026. Nearly the whole Agent Workflow category sits outside its 2019 single-assistant frame.
Google PAIR team
Google Research · 2021 · refreshed 2026-07
Six-chapter first-party guide. Its Explainability + Trust and Feedback + Control chapters map almost one-to-one onto our Trust & Verification and control patterns; its confidence-display guidance ("determine if, when, and how to show confidence") is the softer default our confidence-signals avoidWhen encodes.
Caleb Chan
Nielsen Norman Group · 2025
Recommends against exposing step-by-step reasoning as a trust mechanism: displayed traces are typically post-hoc rationalizations, not the model's faithful process — lean on sources and stated limitations instead. Directly sharpened reasoning-trace's risks framing.
Related Patterns
Curated connections, not just neighbors.
Hand-picked relationships — what this pattern pairs with in practice, what it replaces, what it builds on, and what builds on it.
Often paired with
Disambiguation Branch
Disambiguation Branch asks first when intent is unclear; Capability Boundary says up front what the AI cannot do at all.
Often paired with
Confidence Signals
Capability Boundary says before the run what the AI cannot do; Confidence Signals rate how sure it is of each claim it makes.
Often paired with
Intent Preview
Intent Preview shows the plan before it runs; Capability Boundary flags the parts the AI cannot do and offers a workaround.